Repository navigation
[FEA] Improve cudf::gather scalability as number of columns increases #13509

Description

As the number of columns increases for cudf::gather with the same gather map, we see the number of kernels called increase proportionally and the runtime increases linearly. We are wondering if there are better ways to group or "batch" these calls so we perform less kernel invocations that can do more work all at once, in hopes of amortizing some of the cost with many columns or deeply nested schemas.
A very simple example is below. This creates a column of 10 int32_t rows and adds it to a struct N times (where N is between 2 and 1024):
#include <cudf/table/table.hpp>
#include <cudf_test/column_wrapper.hpp>

#include <rmm/mr/device/cuda_memory_resource.hpp>
#include <rmm/mr/device/device_memory_resource.hpp>
#include <rmm/mr/device/pool_memory_resource.hpp>

#include <memory>
#include <string>
#include <vector>
#include <nvtx3/nvToolsExt.h>

int main(int argc, char** argv)
{
  rmm::mr::cuda_memory_resource cuda_mr{};
  rmm::mr::pool_memory_resource mr{&cuda_mr};
  rmm::mr::set_current_device_resource(&mr);
  using col_t = cudf::test::fixed_width_column_wrapper<int32_t>;

  auto const values = std::vector<int32_t>{1,2,3,4,5,6,7,8,9,10};
  for (int num_cols = 2; num_cols <= 1024; num_cols *= 2) {
    std::vector<std::unique_ptr<cudf::column>> members(num_cols);
    for (auto i = 0; i < num_cols; ++i) {
      auto wrapper = col_t(values.begin(), values.end());
      members[i] = wrapper.release();
    }
    auto struct_col = cudf::test::structs_column_wrapper(std::move(members));
    auto gather_map = std::vector<cudf::offset_type>{1}; // gather 1 row
    std::stringstream msg;
    nvtxRangePush(msg.str().c_str());
    auto result = cudf::gather(
      cudf::table_view{{struct_col}},
      cudf::test::fixed_width_column_wrapper<int32_t>(gather_map.begin(), gather_map.end()),
      cudf::out_of_bounds_policy::NULLIFY);
    nvtxRangePop();
    std::cout << "Result: rows: " << result->num_rows() << " cols: " << result->num_columns() << std::endl;

  }
  return 0;
}
As the column count increases by 2x, the gather kernel takes 2x longer:
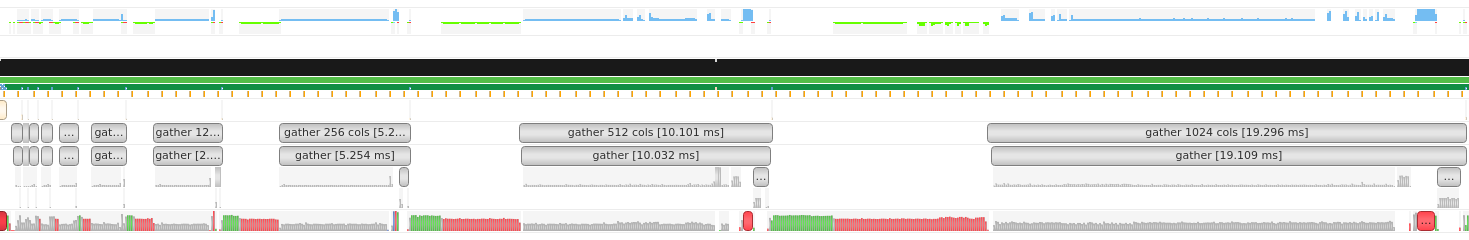
A similar argument can be made for columns that have nested things like arrays of structs (each with array members). The number of calls to underlying cub calls can increase drastically.
I am filing this issue to solicit comments/patches to see how we could improve this behavior.
Metadata
Metadata
Assignees
Labels
Type
Projects
- Status
Activity
abellina commentedon Jun 5, 2023
I also believe, that improving the performance for
gatherwill help withcopy_if(for non fixed width, for fix width it looks like we implement our ownscatterkernel).copy_ifis another kernel with very similar behavior. I think we can discuss what we want here and we can targetcopy_ifas a follow on given what we learn withgather.nvdbaranec commentedon Jun 5, 2023
If we ignore lists and strings for the moment, I think it would be pretty easy to put together a proof-of-concept for doing batched fixed width gathers as a single kernel invocation (well, maybe 2 - one more for validity).
Strings is probably not too hard of an extension. Lists would definitely be tricky. I'd have to wrap my head around the list gather stuff to remember :)
bdice commentedon Jun 5, 2023
At one point cudf (possibly before libcudf!) used a stream pool for gather operations. Each gather is independent, so we can launch all the kernels on separate streams and synchronize them with an event on the input stream. I would love to reimplement this approach and see if it can improve the performance. See also #12086.
lamarrr commentedon Jul 3, 2026
I implemented a batched wide table gather kernel in #21333 and didn't see any performance improvement due to the memory indirection observed in gather implementations. Even with a batched gather kernel, the cost of fetching a row is O(N_rows) due to the serialized memory fetches.
Perhaps a multi-stream gather would improve the scalability.
res-life commentedon Nov 9, 2026
PR #25154 makes a related attempt within
cudf::partition: it batches allocation-size readbacks for eligible non-null STRING columns, shares permutation/inverse maps, and copies multiple STRING columns in one character-copy kernel launch. Per-column offset scans remain separate.This suggests an opportunity to extract reusable permutation-aware batched materialization for other operations that apply the same complete row permutation to multiple columns.
Candidate call sites identified in a source scan:
sort_by_key,stable_sort_by_key, andsegmented_sort_by_keyhash_partitionround_robin_partitionThese are candidates from static inspection, not independently demonstrated speedups. The initial scope could focus on non-null STRING columns and complete permutations, with existing gather paths retained for unsupported cases. Nullable STRING and nested columns need additional care because null rows can contain nonempty physical payloads.
The earlier experiment in #21333 and its reported lack of improvement are useful context: reducing kernel launches alone does not guarantee better performance. The permutation-specific approach also targets repeated allocation-size synchronization and shared map preparation. Benchmarks should isolate these effects and compare against the existing gather implementation across row counts, column counts, string lengths, and permutation locality.
#25154 provides a concrete implementation to evaluate and potentially generalize; its partition results do not establish gains for the other call sites above.
res-life commentedon Nov 9, 2026
Related PR
ttnghia commentedon Nov 9, 2026
I'm working on
cudf::batch_gather, the batch processiong version forgatherthat execute as few kernel as possiblie. Currently in good progress.res-life commentedon Nov 9, 2026
@davidwendt @ttnghia Please help review the potential places needs to do optimization after @ttnghia done cudf::batch_gather.
Link: #13509 (comment)